Here are a few seconds of a finished track. Play it once.
Imagine eight different models each taking this clip. Which of them would hand you back something you could still change one note at a time?
One track, eight jobs
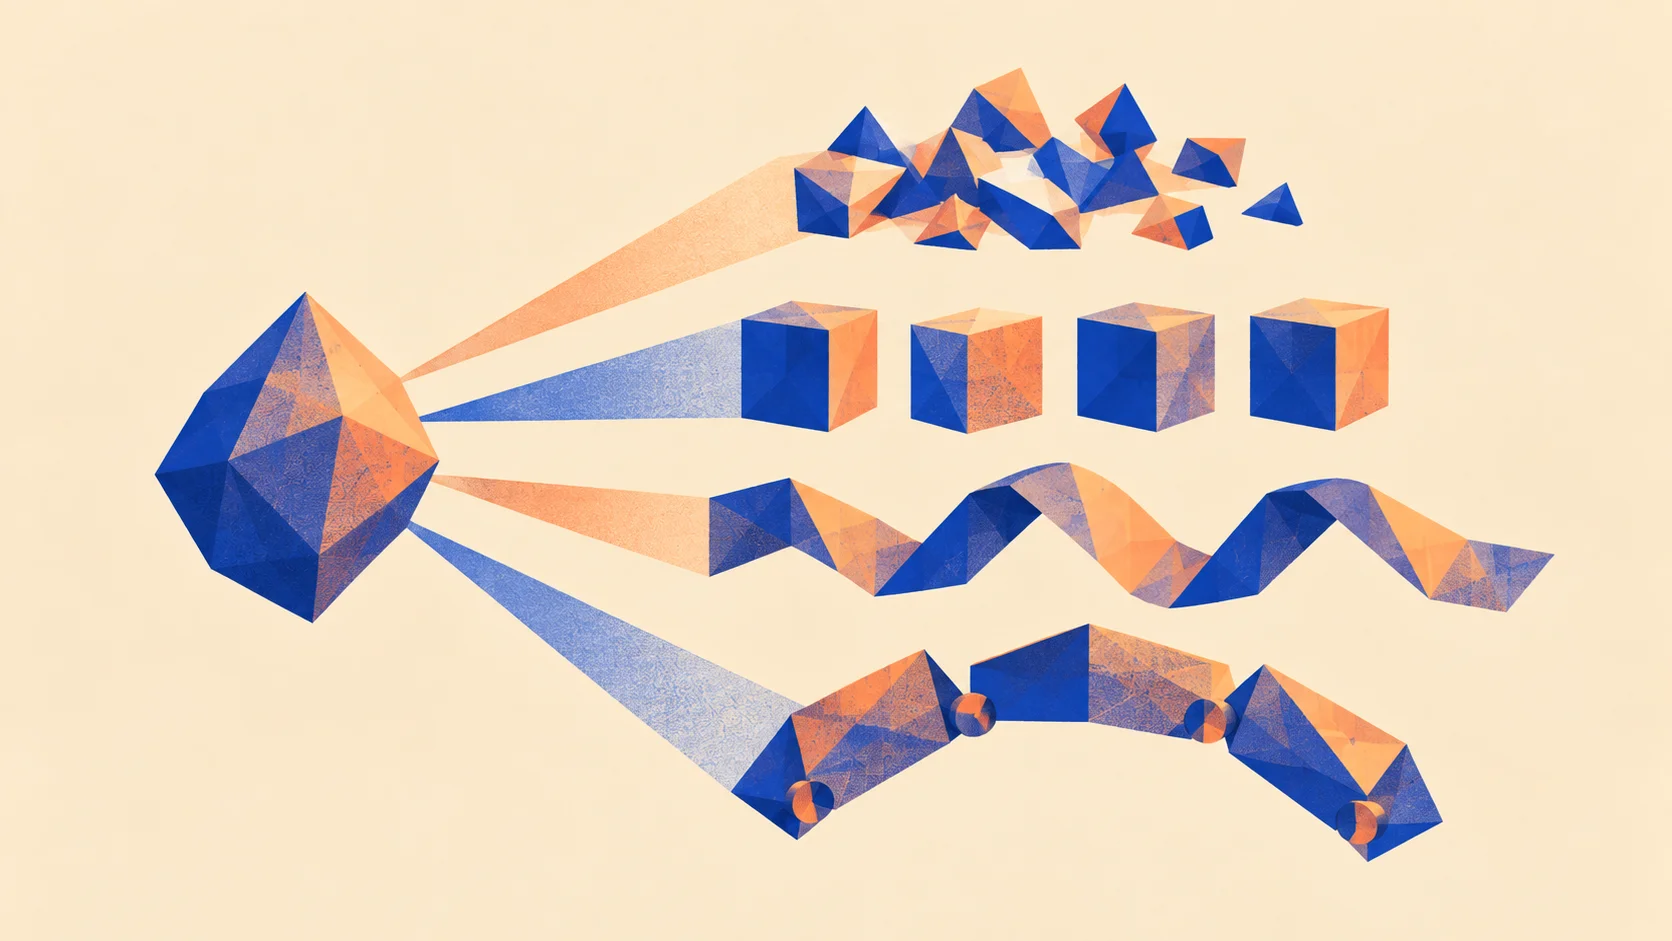
ReplayNow imagine handing that clip to eight different models. One writes down the bass line as notes. One tags it "electronic, energetic, synth bass". One marks every beat and every downbeat. One pulls the drums out on their own. One cleans up a click in the recording. One plays on from where the clip ends. One turns your humming into the lead synth. And one helps you write a new effect to put on it.
Before you read on: which of those eight would give you back something you could still edit note by note?
If you said "the one that writes down the bass line", you're right, and almost alone. The beat marker gives you times you can move. The tags are words. The separated drums, the repaired clip, the continuation and the hummed synth are all audio: you can cut and process them, but there are no notes inside to grab. Same clip, eight jobs, four completely different kinds of result.
People talk about "AI music" as if it were one box you type into. It's really a set of very different jobs, and the most useful question about any of them isn't "which model?". It's this: what goes in, what comes out, and can I still edit it?
Three questions before you pick a tool
Every model in music takes one kind of thing and turns it into another. Learn to name both ends and you can predict most of what a tool will feel like to use.
What goes in, what comes out
- What goes in? A recording, some notes, a sentence, your hands in front of a camera.
- What comes out? Labels (words, times, a key name), notes, a new recording, or a stream of control numbers.
- Can I still edit it? Notes and labels are lists you can fix one item at a time. Audio is a recording: you can cut, stretch and process it, but not reach in and move the third note.
There's a fourth question worth asking every time: where does it run? Some tools run in your browser and your audio never leaves your computer. Others send it to a server. Neither is wrong, but you should know which before you upload an unreleased song.
With those questions in hand, here are the eight roles a model can play. For each one you'll get the musician's job, the name the field uses for it (so you can look it up), and where in Learn to go next.
The listener: hearing what's there
You hummed a melody and want it as MIDI. You want the kicks out of a folder of 3,000 samples, the key of a song before you remix it, or the downbeats in a live recording. The field calls these transcription, classification or tagging, beat tracking and chord recognition. What comes out is a description (notes, words or times), which is why it's the easiest output to fix: a wrong note is one click to delete.
- A sung or played line as editable notes: Audio to MIDI. Spotify's open-source Basic Pitch is a well-known model for it.
- Labelling sounds and finding ones that sound alike: Tagging, search and similarity.
- Finding the pulse and the downbeat: Beat and tempo tracking.
- Naming chords and keys, and why there are often two answers: Chord and key recognition.
The editor: changing what's there
Same recording, but different: just the vocal, the song without the fridge hum, a guitar without its room. The field calls this source separation and audio restoration. Audio goes in and audio comes out, as an estimate, and every edit takes a little of what you wanted with what you didn't.
- Pulling drums, bass and vocals out of a mix: Stem separation, with StemSep, which can run Deezer's open-source Spleeter on your device, as one tool for it.
- Removing noise, room and clicks, and what goes with them: Repair and restoration.
The sound maker: new audio from a description
A snare drier than anything in your library, a pad between a choir and a broken organ, a kit that sounds recorded in one room. The field calls this audio generation, or conditional generation when words or a reference sound steer it. What comes out is a recording: raw material with no notes inside.
- How models make new sounds: Audio generation.
- From a description to a playable kit whose sounds belong together: the project Generate a drum kit. Moodbox plays kits made that way.
The composer: new notes
A melody that continues your four bars, chords under your hook, a drum pattern for the bar you couldn't get right. The field calls this symbolic generation, with continuation and infilling as its two commonest jobs. This is where "can I still edit it?" gets a clear yes.
- Melodies, drum patterns and chords from a model: Generating notes, with Chord Seq as a small example.
The instrument: a sound you play
Here the model is the instrument: you sing and a violin comes out, or you play through a model of one particular amp. The names are neural synthesis, timbre transfer and neural amp modelling. What comes out is live audio, so what you edit is your playing and the settings.
- Instruments whose sound comes from a trained model: Neural instruments and timbre transfer, which you can play in LiveTransfer, built on RAVE, a model family from the IRCAM research institute in Paris.
- Learning a pedal or amp from recordings: Neural amps and captured gear.
- A model of your own source, start to finish: the project An instrument trained on your sound.
- The same idea aimed at a person raises a question no other role does, whose voice is it: Voices, cloning and consent.
The bandmate: playing along
A bandmate listens and answers while you play, so it can't stop and think. The field calls this real-time or interactive generation. Notes usually go in and audio comes out, and you steer it as it happens rather than editing it afterwards. Answering in time is the hardest part, which is why Maru's Accompanist, built on Google's Magenta RealTime 2, keeps its live mode experimental.
- Latency, listening and taking turns: Playing with a model live.
- A part played and answered, step by step: the project Jam with a model.
The sensor: movement into music
Sometimes the input isn't sound: a raised hand opens a filter, held-up fingers pick a chord. That's pose estimation or hand tracking. The model outputs a stream of numbers, and everything musical happens in how you map them, as in Hand Chord.
- Turning movement into control, and smoothing the jitter: Camera and gesture control.
The builder: making the tools themselves
You describe a tool ("a delay that only repeats the snare") and a model writes the code or edits the preset. The field calls these coding assistants or agents. You can edit every line; the hard part becomes checking it does what it says.
- Writing a clear brief and catching claims you can't confirm: Building with an AI agent.
- Putting a model inside your own app: Adding a model to your app.
The whole map on one page
| Role | You want to… | The field calls it | Goes in | Comes out | Edit note by note? |
|---|---|---|---|---|---|
| Listener | write down, label, find the beat or key | transcription, tagging, beat tracking, chord recognition | audio | notes, labels, times | Yes |
| Editor | take a part out, clean a recording | source separation, restoration | audio | audio | No |
| Sound maker | get a sound you don't have | audio generation, conditional generation | words, a reference sound | audio | No |
| Composer | get a melody, chords or a beat to work with | symbolic generation, continuation, infilling | notes, a few settings | notes | Yes |
| Instrument | play a new sound | neural synthesis, timbre transfer, amp modelling | your playing | audio, live | You edit the playing |
| Bandmate | have something answer you | real-time generation | your playing | audio, live | You steer it |
| Sensor | play with your body | hand tracking, pose estimation | camera | control numbers | You edit the mapping |
| Builder | make a tool or preset | coding agents | a description | code, settings | Yes |
Same idea, different place: most useful work chains two roles together, and the output type at the join decides everything. Separate a mix, then transcribe the bass: an editor feeds a listener, and the listener's mistakes land on top of the editor's. Training on your own sounds shows the other way to get a model that fits your music: teach a general one your examples.
Where the map breaks
The roles are a map, not a rulebook, and they blur in three places worth knowing.
Audio that sounds like notes isn't notes. You heard this at the top: a clear melody in a recording still has to be transcribed, with new guesses, before you can move a note.
One model can play several roles. A model that learned what drums sound like might be used to separate them, to tag them or to generate new ones. The role is set by what you ask of it, not by the model itself.
Every role inherits its training. A separator trained on rock mixes has its own idea of what "drums" are, and a tabla might not fit it. How models see audio explains why the picture a model works from also limits what it can notice at all.
Make it yours
Pick three jobs from your own music that you'd consider handing to a model: anything from "find the key of this sample" to "give me a bass line under these chords". For each, fill in the sheet below before you look for any tool. You'll often find that the answer to "can I still edit it?" changes which tool you want.
For each job, what will you give the model, what will you get back, and can you still change it afterwards?
What goes in, what comes out
0 of 3 done · saved in this browser
Keep the sheet. When a new tool appears with a big claim, you'll be able to place it on the map in a few seconds, and know what you'll be holding when it's done.
Quick check
- You've found one snare you love and want twenty more like it from your sample folder. Which role, and what comes back? A listener. A similarity search measures where each sample sits and returns the nearest ones: a ranked list you can audition, not new audio. A sound maker could generate new snares instead, but you'd be judging recordings that didn't exist before rather than ones you already own.
- A tool separates a vocal from a song, and you then run a transcriber on the vocal to get the melody. The MIDI has odd extra notes. Whose mistake is it? It could be either, and that's the point of chains. The separated vocal may carry a little of the guitar, and the transcriber may write those leaked notes down faithfully. Listen to the separated vocal first: if you can hear the guitar in it, start there.
- A plugin listens to your keyboard and plays a drum groove that follows your dynamics, live. Which role, and what can you edit? A bandmate. What comes out is audio, live, so you steer it with your playing rather than editing it afterwards. If you need a drum part you can edit later, you'd want notes from a composer, or a recording of the result to work on.
Next steps
- Go deeper: What an audio model learns. Every role on this map runs on habits learned from examples. What exactly does a model learn, and why do its mistakes follow the sound so predictably?
- Use it: Beatbox to drum pattern. Chain a listener and a composer: turn mouth sounds into a drum part you can edit, and see where the output type at the join matters.
- Sideways: Music as data. Every input on this map is music turned into data first. What does a count or a table keep, and what does it throw away?